 senn-tech
Enterprise AI stack, built in-house
Reference client: Own operations: the studio's in-house AI infrastructure
Customer data in copy and images has been neutralised.
Four hosts, three roles
Five weeks, host by host
Dates are the real ordering here; this is a change log and not a countdown. Each entry is a decision that was actually made and measured and not a plan.
A single huge MoE model, swapped morning and evening by a cron job. The switcher outlived the model it was written for and kept trying to resurrect it for weeks after the fleet had moved on.
Several models in turn (Qwen3-VL, then a dense Qwen3.8-27B) read invoice and delivery-note images before the pipeline moved to routing everything through the gateway.
Qwen3.6-35B-A3B, a genuinely different architecture (MoE rather than dense), used as the fourth independent vote in the document pipeline. Briefly also hosted the briefing bot, 08-28 to 09-01.
Deterministic markdown and table parsing for the document pipeline's anchor lane.
A deterministic transcriber alongside the two LLM lanes: an LLM can invent a digit, a transcriber can't. Since then embed, rerank, Docling and mocr share this card, quietly full at 15.4 of 16.4 GB and ~0% GPU load.
The dense 27B replaces the 122B MoE. First time all seven legacy names (vision, text, gemma, gemma-4, qwen3.8-27b, thinking, nothink) point at one model.
Qwen3.8-27B-AWQ-INT4, turboquant KV. A whole card for one Telegram bot, deliberately kept apart from LibreChat traffic.
Freed for another project. First stop on the bot's three-host, three-week tour.
A safety net so thinking and nothink didn't go dark while the main host was tied up testing Flash-Next.
Community fine-tune, dynamic FP8 quant. Matched the FP8 baseline's 18 of 21 battery score, improved tool-calling and vision, leaner output.
A new architecture tested across all four cards via llama.cpp. Solo throughput was excellent; concurrent throughput collapsed (see the numbers below). Production chat ran on the standby for the duration of the test.
Its AMD card on the head node was being physically removed. The bot returns here on llama.cpp, Cold-Fusion-GAIN IQ4_XS with a native MTP head.
Passthrough freed for another project. This is the moment the pipeline's fourth independent vote quietly went away.
The GGUF had been running without its vision projector the whole time. Every image request had been failing silently. One missing file, found and fixed.
Chat lanes move back to the main host permanently. The bot itself is parked; its cron and agent jobs migrated to dsh the same day. This card's job today: sit quietly and catch thinking/nothink if the main host errors or times out.
Same new model family, moved to vLLM where concurrent requests actually bundle. An FP8 KV-cache patch nearly doubled concurrency at the same context length.
262,144 tokens, the same ceiling the 2026-08-19 model reached, this time on the new family, genuinely at its real maximum.
93 ROCm/HIP/HSA packages, 9 amdgpu/libdrm packages, 22 GB gone. This host now runs LibreChat, LiteLLM, the auto-router, the document pipeline, dsh and ~15 MCP sidecars, and not one GPU workload.
Starting point
Running your own AI models on your own hardware means making every decision a rented API would otherwise make for you: which model, how much context, which card, which fallback path. In return, the data stays in-house, and nobody else decides when a model gets retired or swapped.
This reference comes from our own operations: the fleet that carries LibreChat, our own agents, and internal document processing every day. When a card here hits its limit, we find out first and not a customer left waiting.
The hard part
It started with a single large model that a cron job swapped morning and evening. That held up right until the schedule outlived the model: the switcher kept trying to resurrect a model that had long since been replaced, weeks after the fact, because nobody had told it otherwise.
A second card read documents for invoice processing, deliberately on its own independent model architecture, so two readers wouldn't sit on the same foundation and be wrong together. That card was specialised hardware incompatible with the rest of the fleet, and it had to make way for another project.
A third service, a Telegram bot for the daily briefing, moved across three different cards within three weeks, always to wherever capacity happened to be free. On the last one it ran blind for five days, because a single file (the vision module) was simply forgotten during the move. No error, no warning, just an answer that never matched the picture.
Solution
The fleet today runs a single model family across every chat lane (reasoning on, reasoning off, agent traffic, document vision) from one host with four graphics cards, instead of seven different model names for seven different purposes.
If the main host fails or takes too long, a second card with the same model family steps in automatically: smaller context, different quantisation, but nothing a user would notice.
The small, constantly-used services (embedding for search, re-ranking results, text recognition) now sit together on one small card instead of scattered across the fleet.
How it is built
A gateway is the only thing any caller talks to: LibreChat, the agents, internal automation, even the CNC line on the shop floor. Which card actually answers stays hidden behind it, and that's exactly what makes the fallback possible without any client ever needing to change.
The road to today's 262,144-token context wasn't a straight one. A new model first needed a lower, more honest ceiling, because the old maximum no longer applied to the new architecture, a mistake that would otherwise have surfaced only at the first conversation that got cut off. A patch to the cards' cache format then nearly doubled concurrent capacity, from 3.2 to 5.9 full-length conversations, before context was raised back to its real maximum.
A different piece of serving software for the same new model looked excellent running alone and collapsed to less than half its solo throughput under eight concurrent requests. What runs today instead saturates past 30 concurrent conversations rather than collapsing at eight. That comparison alone decided which serving software the fleet runs.
In document processing, four independent readings vote on every field: two language models, two deterministic text-recognition passes. Since the specialised card was retired, two of those four votes now share the same server. That's documented openly and not glossed over: it's three independent opinions today and not four.
Every lane, what backs it, what it's for
| Lane | Backend | Status | Purpose |
|---|---|---|---|
| thinking | main:8000 | primary | Main chat lane, reasoning on. LibreChat and all 29 agents. |
| nothink | main:8000 | primary | Same model, reasoning off: clean JSON, tool-heavy flows. |
| dsh | main:8000 | primary | Identical backend to thinking, its own spend-log row for agent-job traffic. |
| vision | main:8000 | primary | Alias for callers still asking for “vision” by name. No separate vision model exists any more. |
| thinking-cnc | main:8000 | primary | CNC runner with a 30-minute timeout; the default 600 s killed long jobs at 601 s. |
| cnc-nothink | main:8000 | primary | Same runner, reasoning off when overthinking derails the CNC task. |
| text(Alias) | → nothink | hidden | Legacy name, transparently mapped. |
| auto(Alias) | → thinking | hidden | Legacy name, transparently mapped. |
| thinking-fallback / nothink-fallback | standby:8080 | fallback | Auto-failover if the main host errors or times out. Smaller context, INT4 not FP8: continuity and not parity. |
| embed | helper:8010 | primary | RAG / vector search. |
| rerank | helper:8011 | primary | RAG result re-ranking. |
| mocr | helper:8123 | primary | Deterministic OCR, also the document pipeline's fourth voting lane. |
| hermes | standby:8080 | parked | The briefing bot, retired 2026-09-03, jobs migrated to dsh. |
| security | standby:8081 | defined, off | Abliterated red-team model, commented out and not live. |
Four lanes vote on every document
The document pipeline reads invoices and delivery notes for ERP and TMS import. Each lane extracts independently; a reconciler picks the consensus value per field.
3 independent opinions instead of 4. Vision and text both resolve to the same backend (nothink on the main host) since the 2026-08-19 gateway cutover: one LLM reads twice, plus two genuinely separate deterministic parses (Docling, dots.mocr).
No quick fix: the old dedicated vision backend (the AMD R9700's vision-moe) was physically removed 09-01 and its software stack purged 09-07. Restoring true four-way independence means standing up a new backend and not flipping a setting.
The two decisions the numbers actually made
Concurrency on the main lane (main host)
KV-cache pool size, expressed as a multiplier of full-context requests it can hold at once
The dashed segment is a model-family swap and not a tuning step; concurrency should reset there. The two solid segments are the same model family: the FP8-KV patch nearly doubled concurrency, and reaching the true 262k ceiling cost some of that back.
Why the main lane ended up on vLLM
Same Flash-Next-class model, two serving engines, tokens per second
llama.cpp was faster solo and slower bundled than itself: eight concurrent streams totalled less throughput than one. vLLM saturates instead of collapsing, which is the whole reason the main host runs it.
Day-to-day operation
A watchdog script automatically restarts stopped services, useful, until it misidentified a model and resurrected one that had long been replaced. The rule since is as simple as it is strict: a service only counts as 'should be running' if its own restart policy says so too.
The automatic fallback isn't just configured, it's regularly tested for real: the main host gets deliberately knocked out, and the only thing that counts is whether the second one actually takes over and not whether the configuration looks plausible.
Outcome
Every chat lane now runs on one model family with automatic failover, at a native context ceiling of 262,144 tokens: measured and not claimed.
The fleet's former head node no longer carries a single graphics card; its entire specialised driver stack was removed, freeing 22 GB of disk.
What we learned
On a self-run AI stack, the hardware is the smaller job. Almost every fault during those five weeks of rebuilding was not a failed card but a rebuild where something got left behind. Maintenance now follows a short checklist rather than experience.
We now re-measure which model actually runs behind which name, on a schedule. We did that systematically for the first time while writing this report, and the result did not match the configuration. The measurement has been part of maintenance ever since and not part of the write-up.
Four cards cover our daily load. The limiting factor is not compute but the maintenance time left over alongside operations. Anyone planning a self-run AI stack should cost those hours first, since they decide whether the setup is still current in two years.
Other projects we run
Company AI portal on its own GPUs
ChatGPT comfort in-house: 5 models, 32 tools, ~90 user accounts. Chats and documents stay in-house.
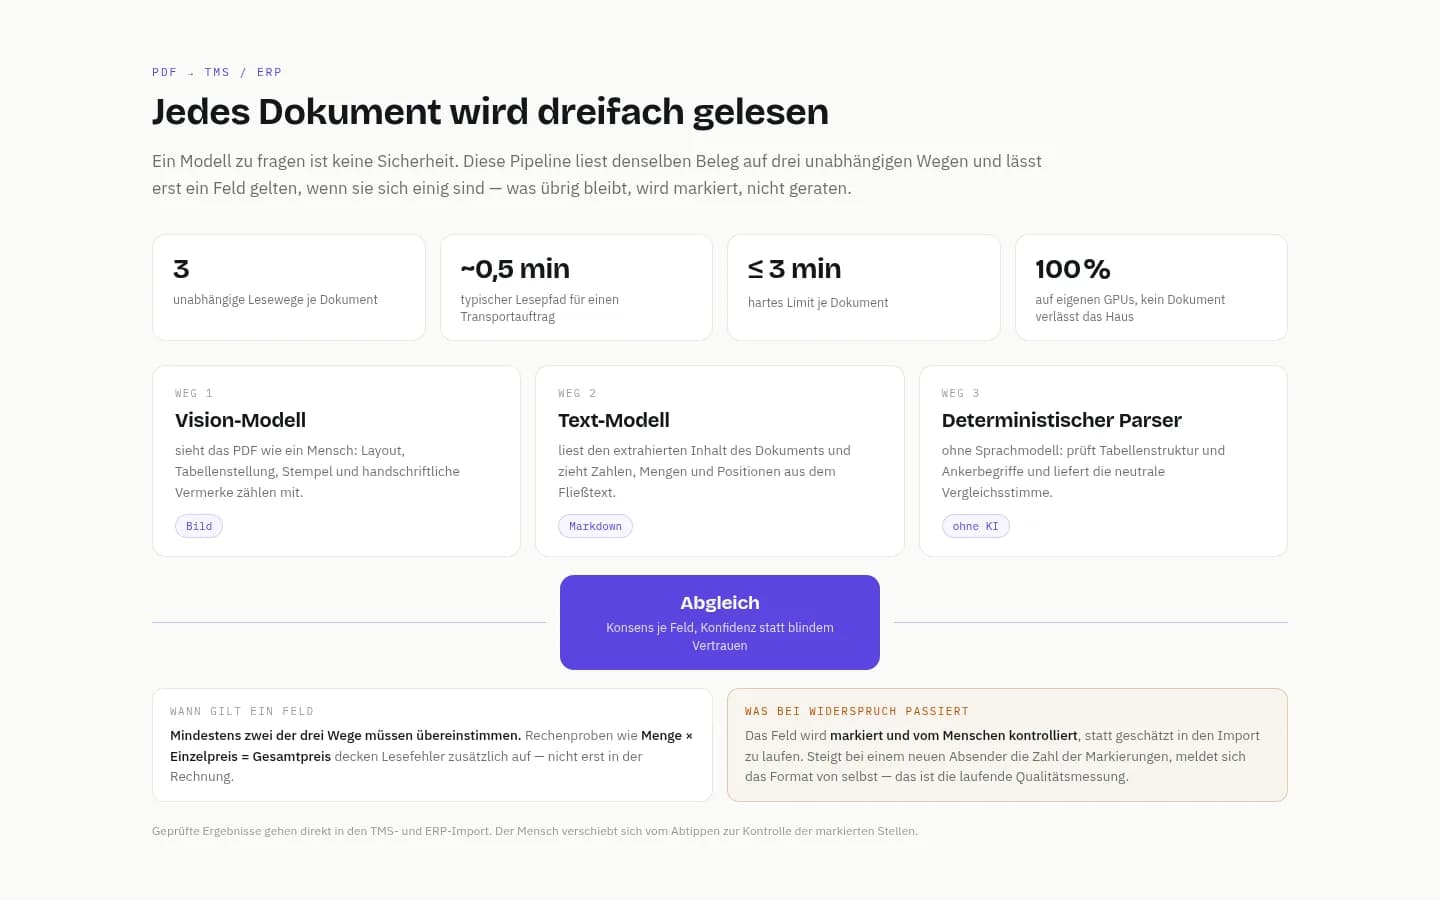
AI document processing with consensus checking
PDFs read three ways (vision model, text model, rule engine) and only written to the ERP when they agree.
Similar problem?
Tell us what you're planning, a short call clarifies whether it pays off.